Volume I · Bttr. Field Guides
Est. 2026 · Updated weekly
Bttr.
Field
Guides.
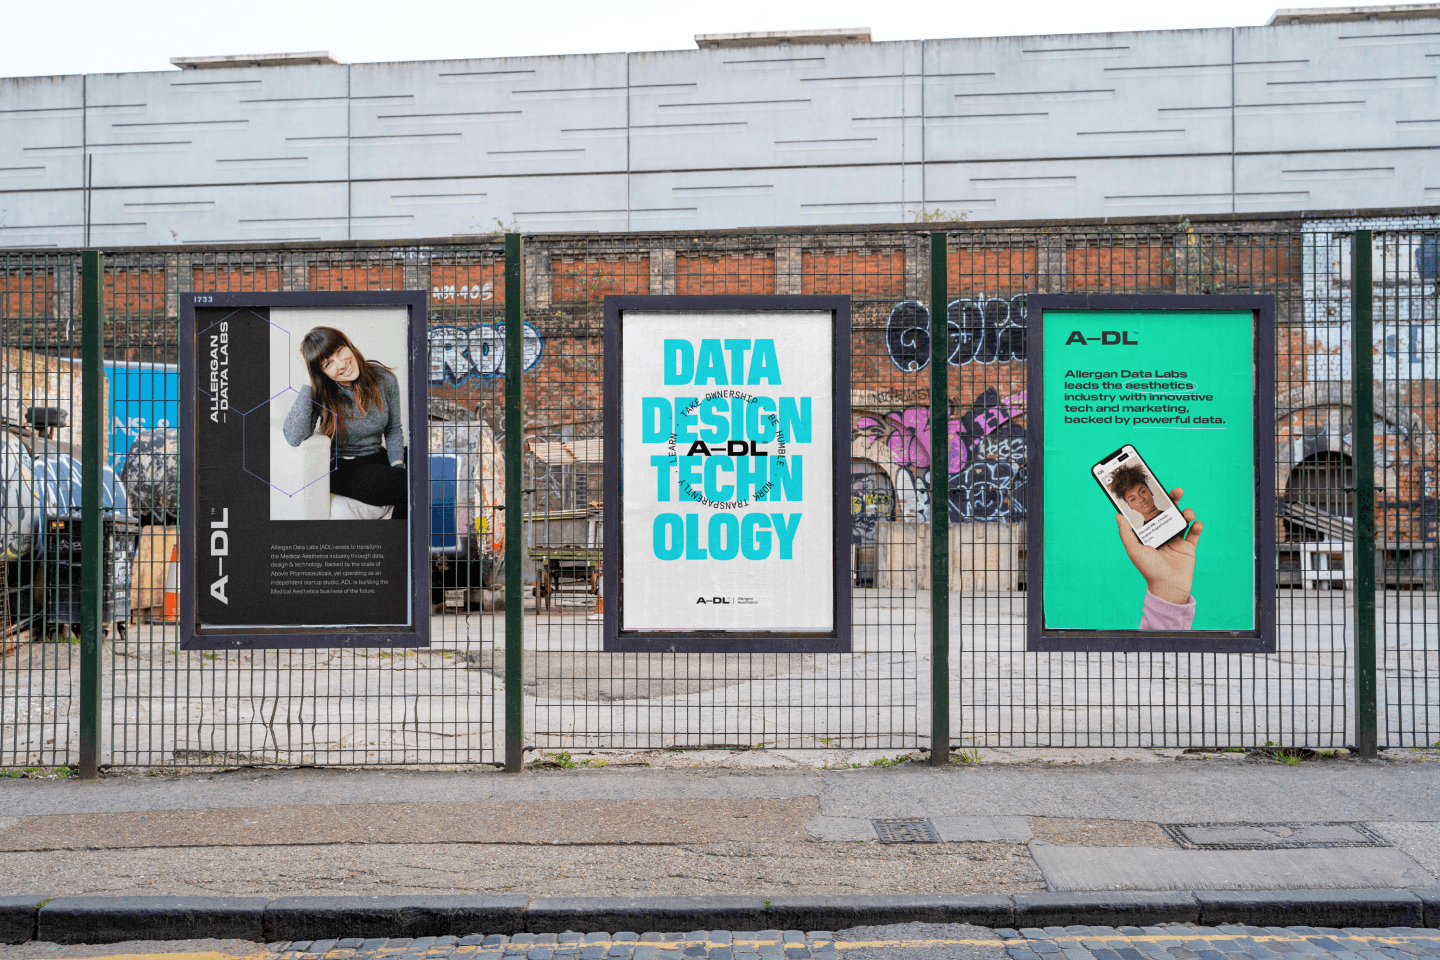
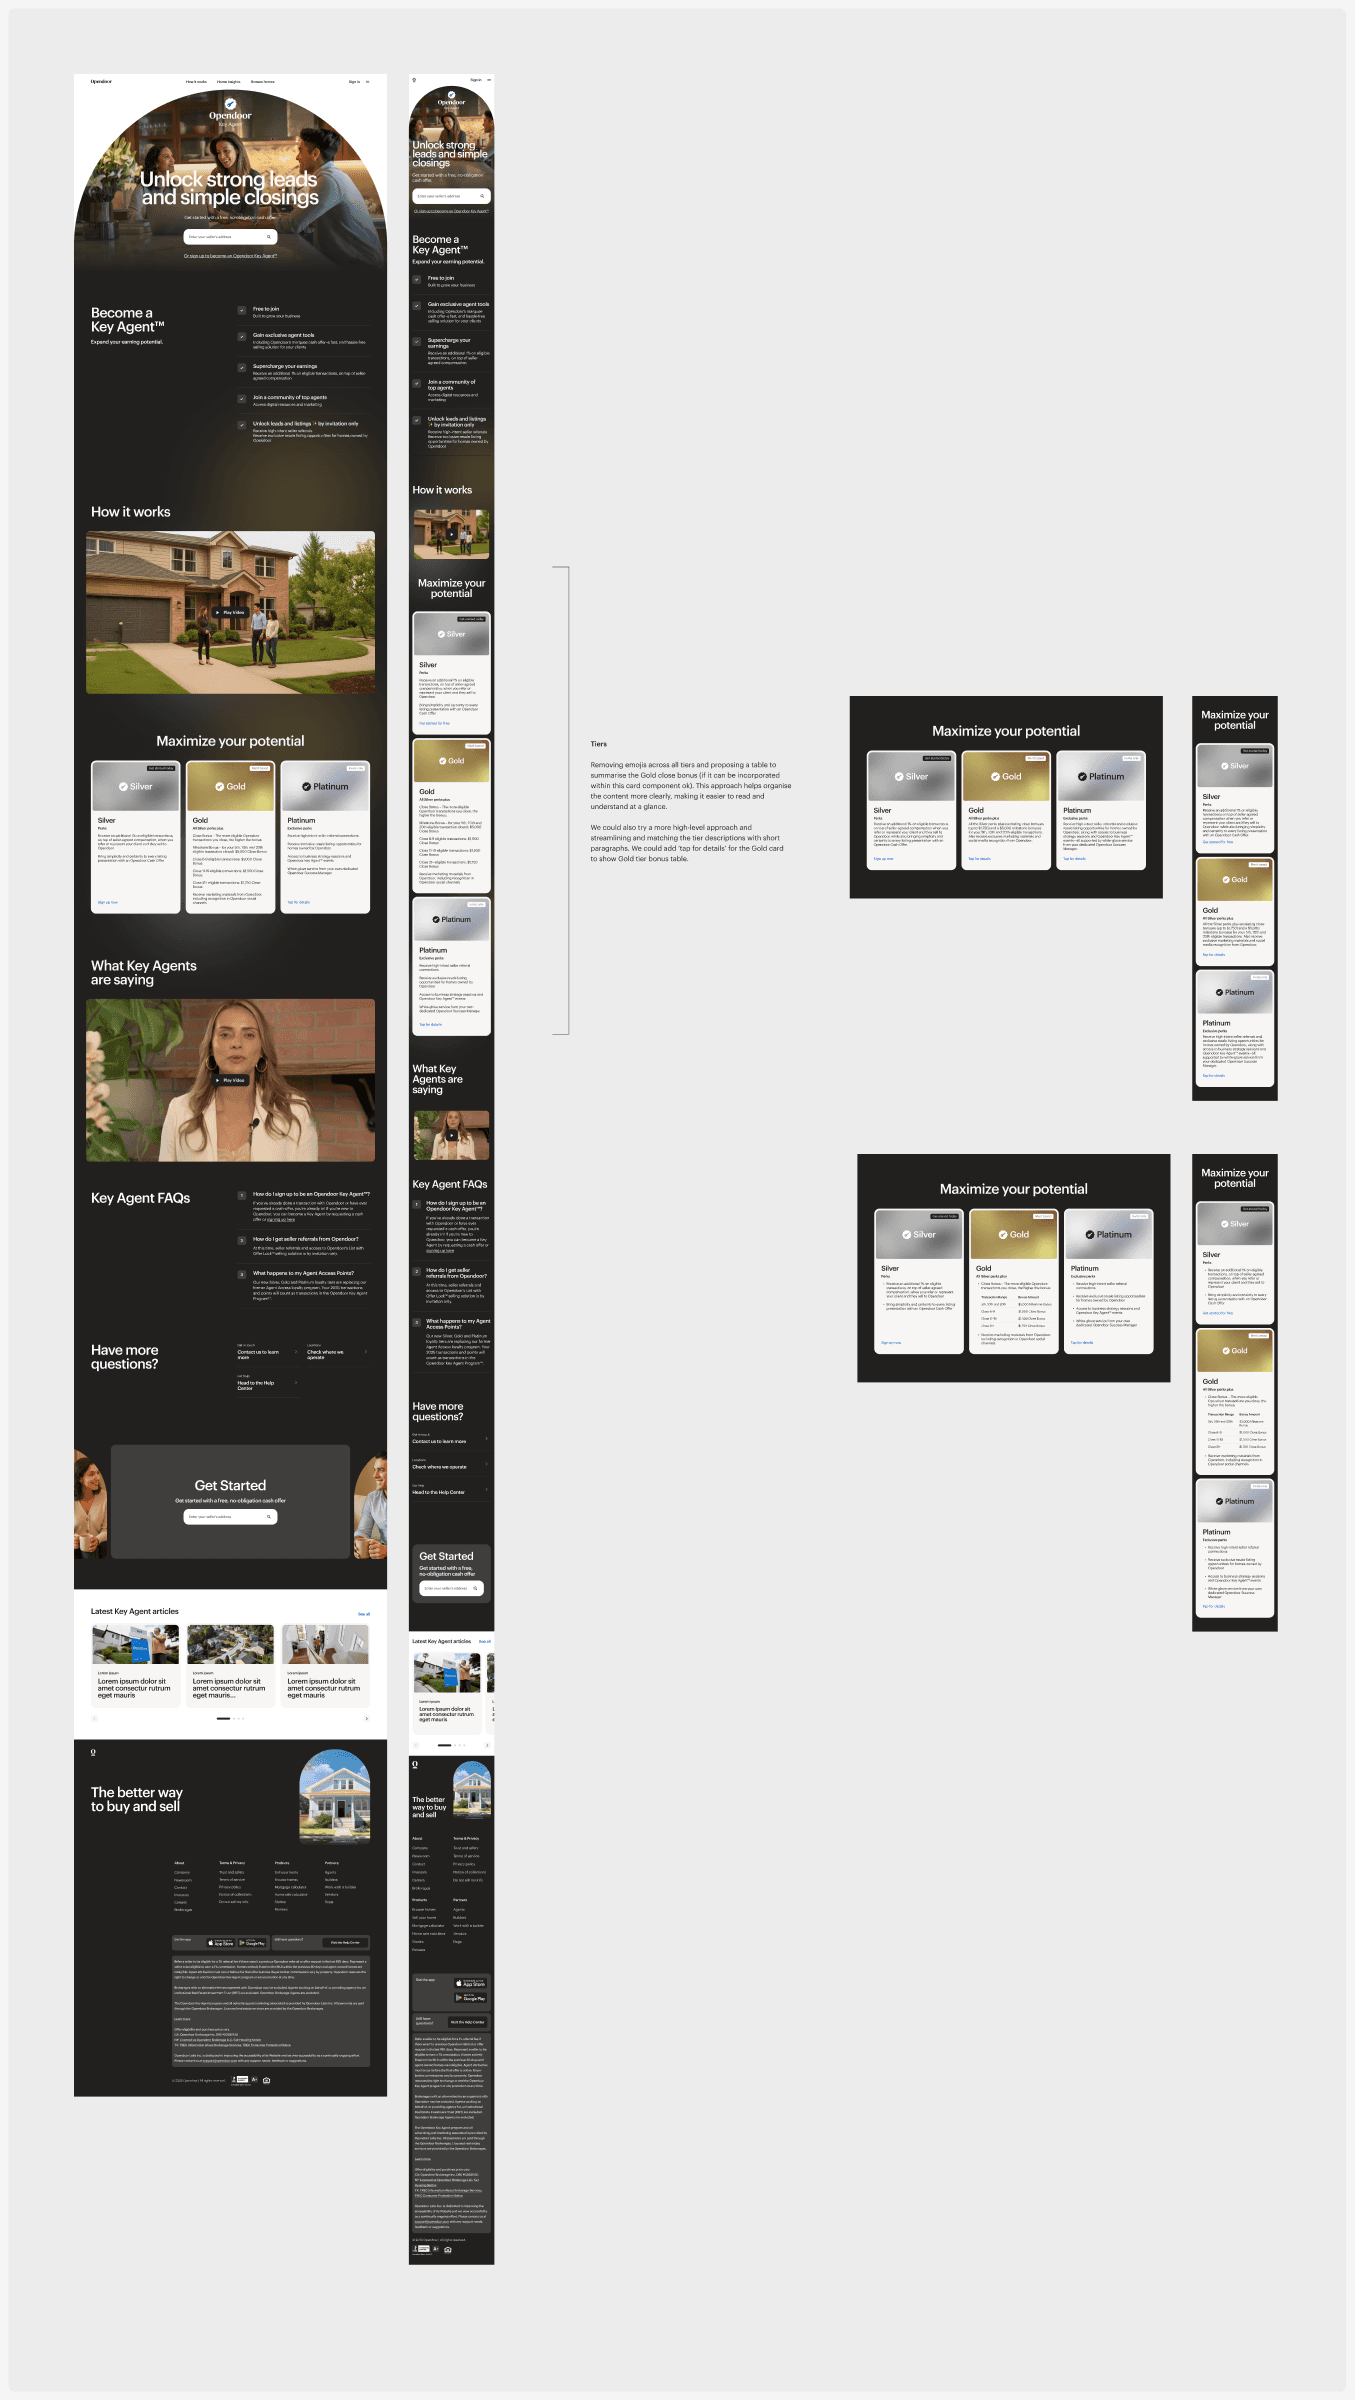
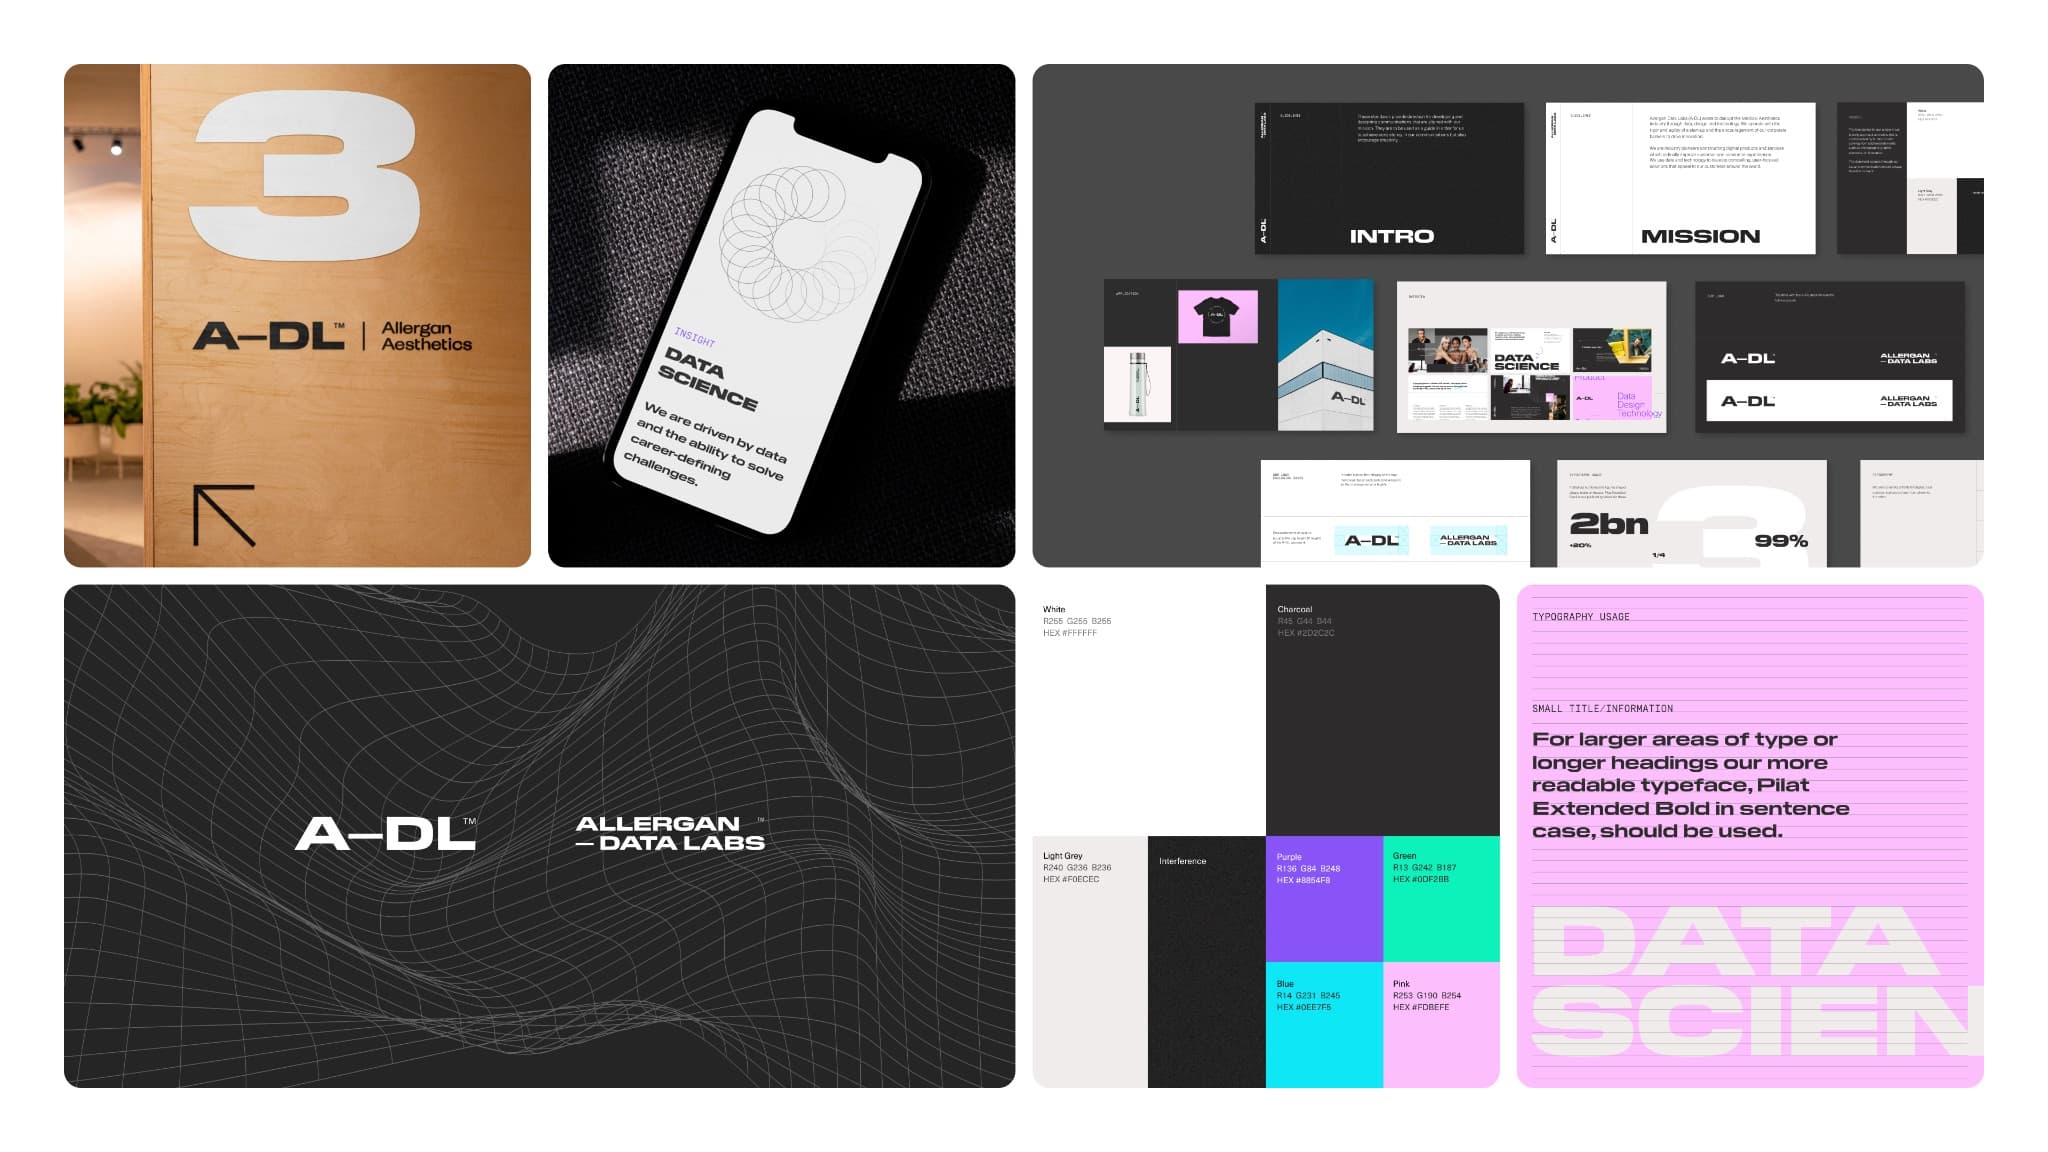
The canonical knowledge layer for AI native enterprise systems. Definitional pillars, named frameworks, live benchmarks, and field reports · built from real engagements at GE Aerospace, Allergan Aesthetics, Tiger BioSciences, GE Vernova, and Ross J Barr.
Written for senior buyers · No filler · Cite as you wish
76
Field guides
4
Topical clusters
1
Live benchmark
Weekly
Cadence
Start here · The four definitional pillars
04 / 04
What Is a Brand Operating System?
The connected set of decisions, components, and rules that lets every team ship one coherent brand.
ReadWhat Is a Brand Sprint?
A fixed timebox engagement that compresses a quarter of brand work into four to eight weeks.
ReadWhat Is AI Search Visibility?
Whether your brand surfaces when users ask ChatGPT, Perplexity, Claude, and Gemini about your category.
ReadWhat Is an AI Product Design Agency?
An agency that designs, builds, and operates AI native product surfaces. Distinct from a traditional design studio.
ReadBrowse by cluster
Four clusters. One canonical knowledge layer.
Every field guide on this page belongs to one of four topical clusters. Each cluster has a definitional pillar, supporting pages, comparisons, and (where it applies) a named framework.
AI Search Visibility
15 pages
How AI engines cite brands.
The AI Visibility Stack, the Citation Index, the Brand AI Scanner, four per engine deep dives, GEO vs SEO, six industry pillars.
Brand Operating Systems
9 pages
How modern brands operate at scale.
The Brand Operating System Framework, the definitional pillar, comparison and implementation guides, plus the 30 item checklist.
Industry & Regulated
9 pages
AI Visibility and software, per vertical.
AI Visibility for Aerospace, Biotech, Medical Devices, Healthcare, Energy, and the regulated umbrella · plus the matching software-development field guides.
POV & Frontier
4 pages
Where the work is going.
Long form essays on AI native operations, regulated product UX, the AI infrastructure buildout, and the shifts that change the work.
September 30, 2026 · 8 min read
What Is Chunking in RAG
A retrieval system never reads your whole document. It reads the passages you cut it into, and chunking is that cut. Split too coarse and one chunk carries three ideas, so its embedding blurs and the right query misses. Split too fine and a passage loses the context that made it mean anything, the way a line reading the company revenue grew by 3% no longer says which company or which quarter. There is no universal size. LangChain base text splitter defaults to 4,000 characters, LlamaIndex sentence splitter to 1,024 tokens, because the right cut depends on your documents and your queries. Anthropic reported that adding a short generated context to each chunk before embedding cut the failure rate for the top 20 retrieved chunks by 35%, and by 67% once reranking was stacked on top. Retrieval quality does not start at the model. It starts at the cut.
76 insights




Bttr. Field Brief
The brief Bttr. writes for senior buyers.
Monthly. One field guide worth your time on Brand Operating Systems, AI search visibility, and the infrastructure buildout. Written by Donny Smith. No filler.
We design, build, and run digital systems for the science, aerospace, and biotech industries.