Volume I · Bttr. Field Guides
Est. 2026 · Updated weekly
Bttr.
Field
Guides.
The canonical knowledge layer for AI native enterprise systems. Definitional pillars, named frameworks, live benchmarks, and field reports · built from real engagements at GE Aerospace, Allergan Aesthetics, Tiger BioSciences, GE Vernova, and Ross J Barr.
Written for senior buyers · No filler · Cite as you wish
67
Field guides
4
Topical clusters
1
Live benchmark
Weekly
Cadence
Start here · The four definitional pillars
04 / 04
What Is a Brand Operating System?
The connected set of decisions, components, and rules that lets every team ship one coherent brand.
ReadWhat Is a Brand Sprint?
A fixed timebox engagement that compresses a quarter of brand work into four to eight weeks.
ReadWhat Is AI Search Visibility?
Whether your brand surfaces when users ask ChatGPT, Perplexity, Claude, and Gemini about your category.
ReadWhat Is an AI Product Design Agency?
An agency that designs, builds, and operates AI native product surfaces. Distinct from a traditional design studio.
ReadBrowse by cluster
Four clusters. One canonical knowledge layer.
Every field guide on this page belongs to one of four topical clusters. Each cluster has a definitional pillar, supporting pages, comparisons, and (where it applies) a named framework.
AI Search Visibility
15 pages
How AI engines cite brands.
The AI Visibility Stack, the Citation Index, the Brand AI Scanner, four per engine deep dives, GEO vs SEO, six industry pillars.
Brand Operating Systems
9 pages
How modern brands operate at scale.
The Brand Operating System Framework, the definitional pillar, comparison and implementation guides, plus the 30 item checklist.
Industry & Regulated
9 pages
AI Visibility and software, per vertical.
AI Visibility for Aerospace, Biotech, Medical Devices, Healthcare, Energy, and the regulated umbrella · plus the matching software-development field guides.
POV & Frontier
4 pages
Where the work is going.
Long form essays on AI native operations, regulated product UX, the AI infrastructure buildout, and the shifts that change the work.
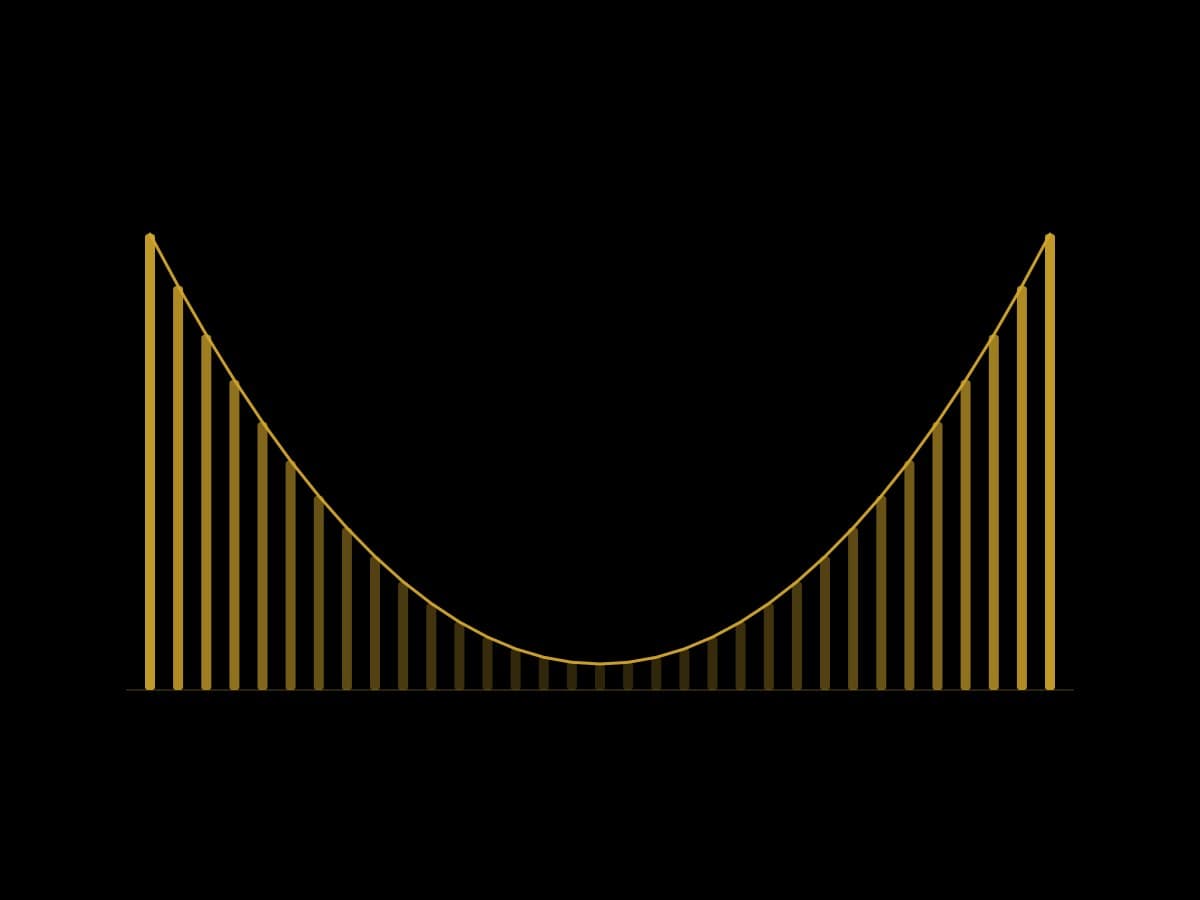
September 12, 2026 · 8 min read
What Is Context Rot
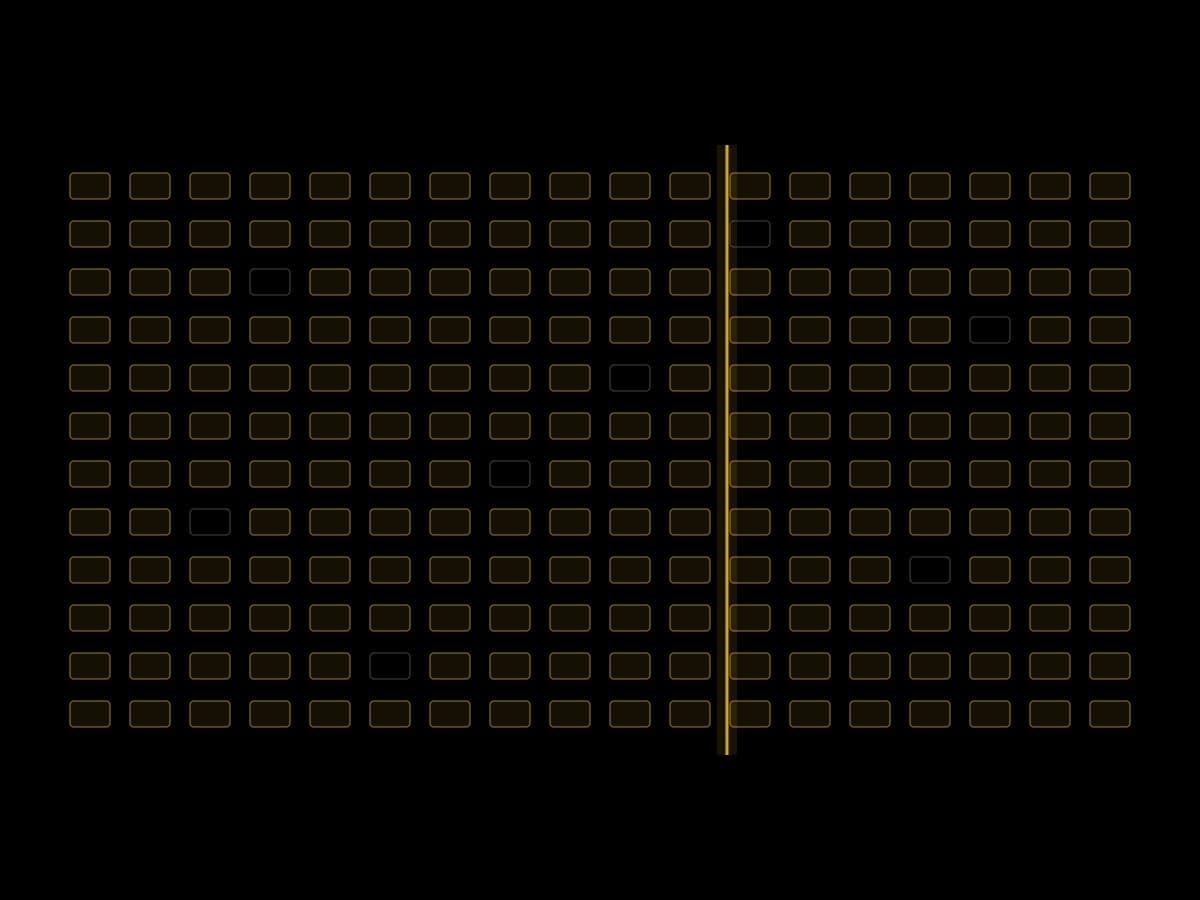
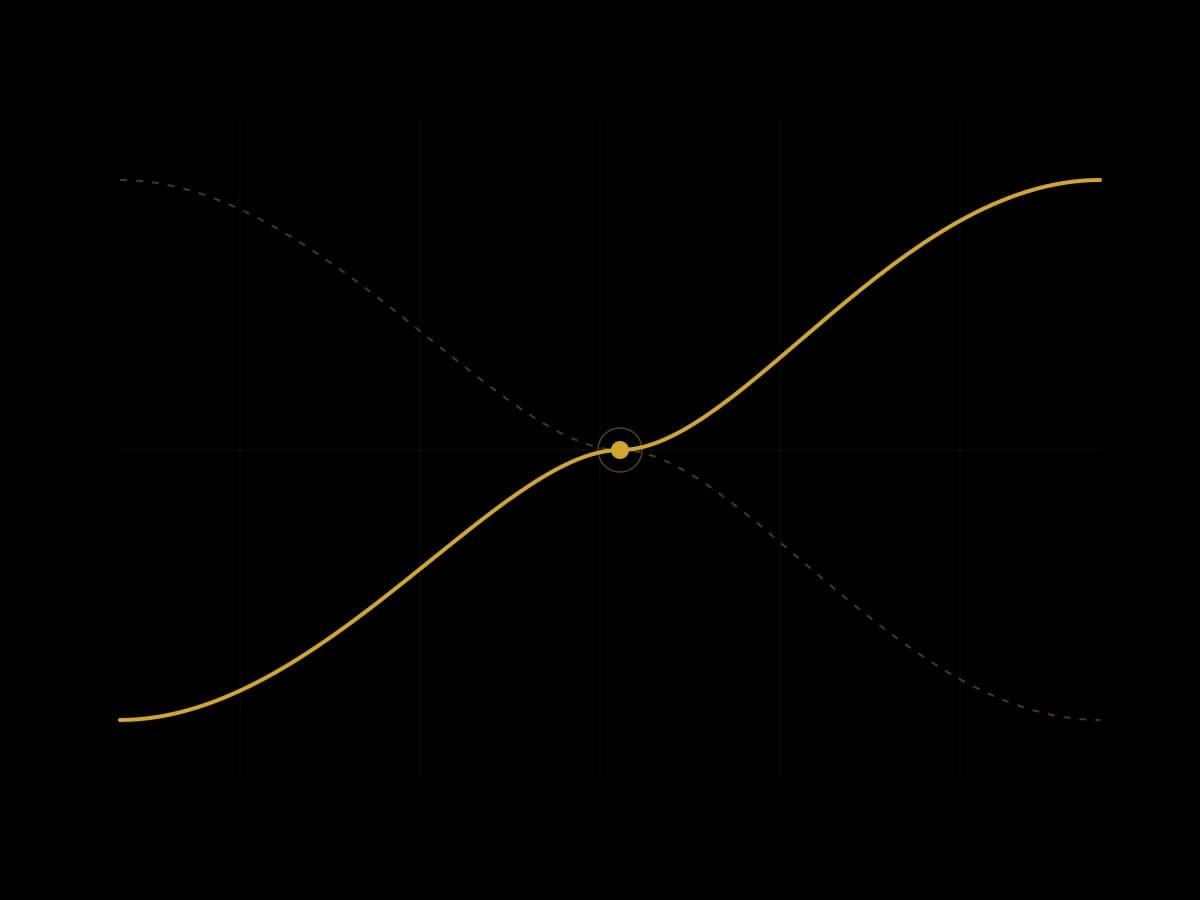
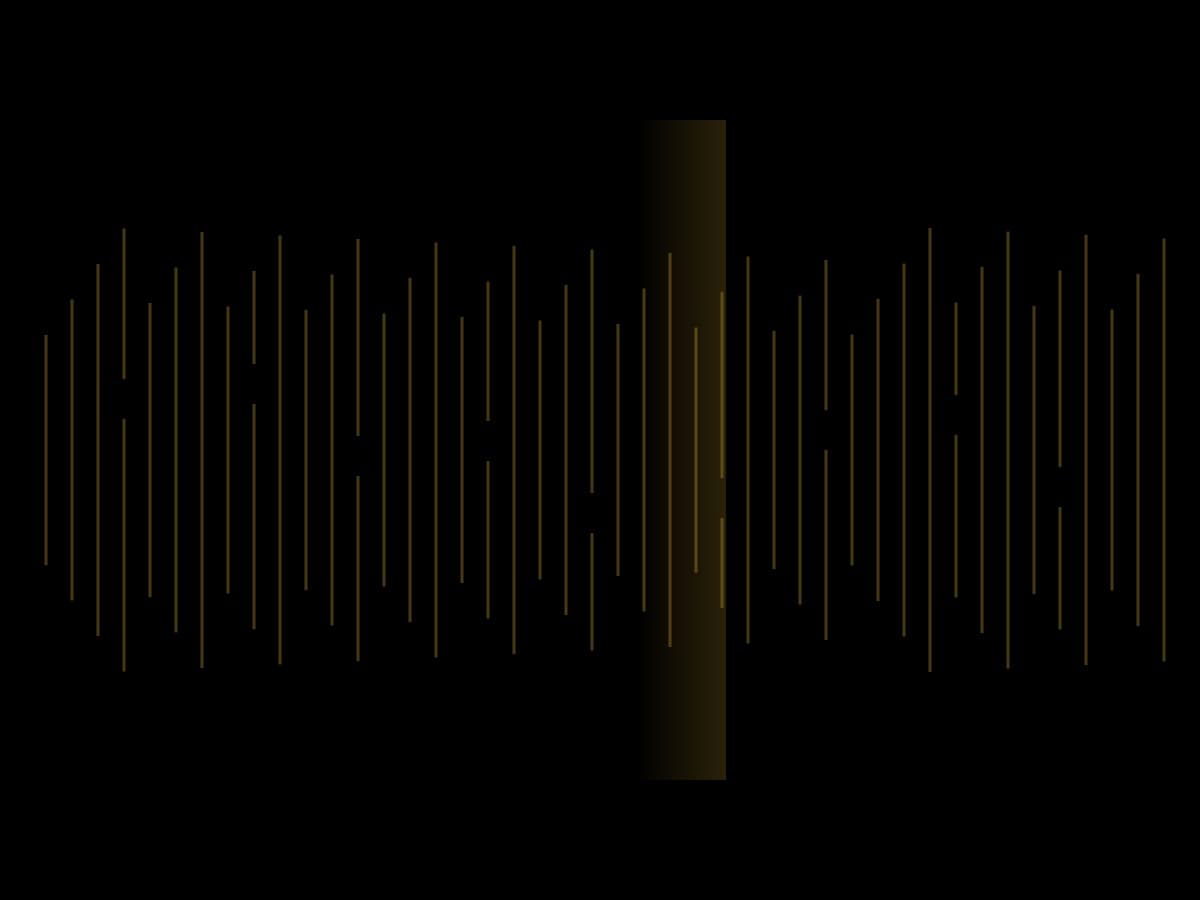
A model with a million token window still does not read it evenly. It handles the front and the back with care and grows careless in the middle, and the more you load in, the wider that careless zone gets. That is context rot, the measurable drop in quality as the input grows, and it starts long before the window is full. In a July 2025 report, Chroma tested 18 current models, among them GPT 4.1, Claude 4, Gemini 2.5, and Qwen3, and found every one got worse as the input got longer, even on finding a fact or copying text. Two years earlier a Stanford team named the lost in the middle effect, where accuracy fell more than 30 percent when the answer sat in the middle rather than the edges. What context rot is, why a bigger window is not a bigger memory, and the smaller cleaner window that fixes it.
67 insights




Bttr. Field Brief
The brief Bttr. writes for senior buyers.
Monthly. One field guide worth your time on Brand Operating Systems, AI search visibility, and the infrastructure buildout. Written by Donny Smith. No filler.
We design, build, and run digital systems for the science, aerospace, and biotech industries.