Volume I · Bttr. Field Guides
Est. 2026 · Updated weekly
Bttr.
Field
Guides.
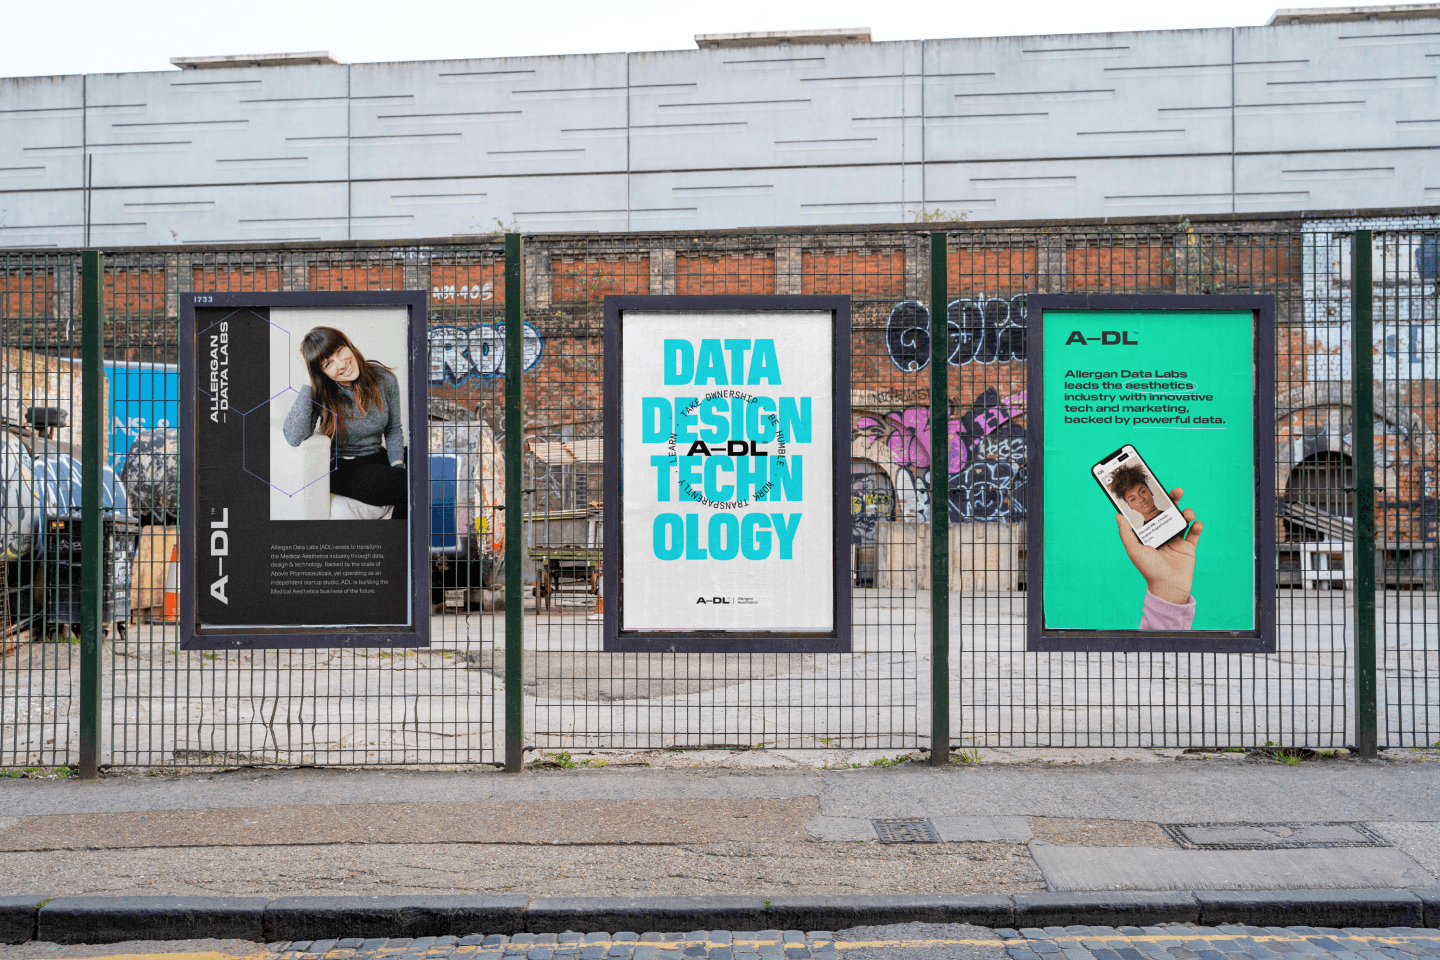
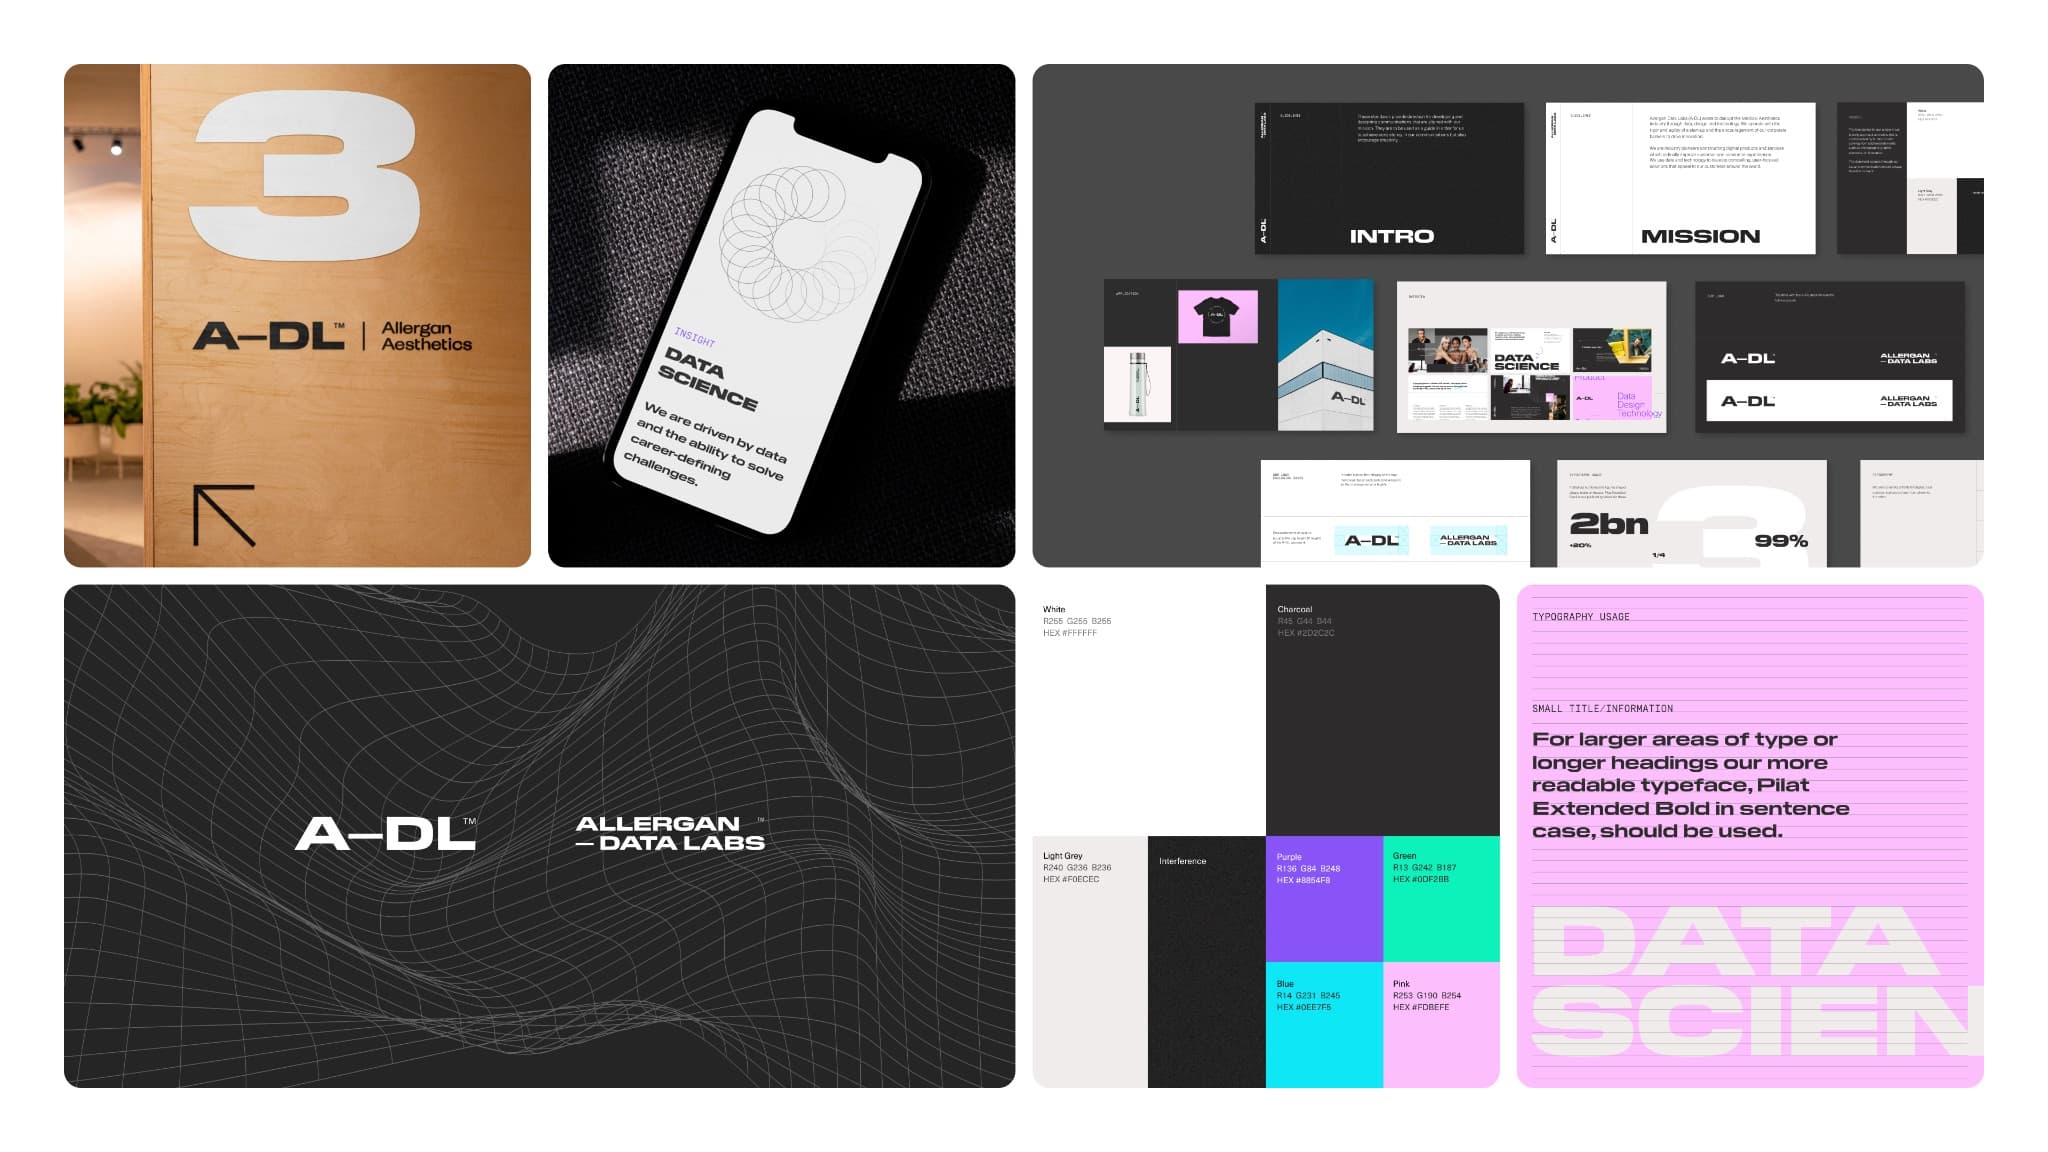
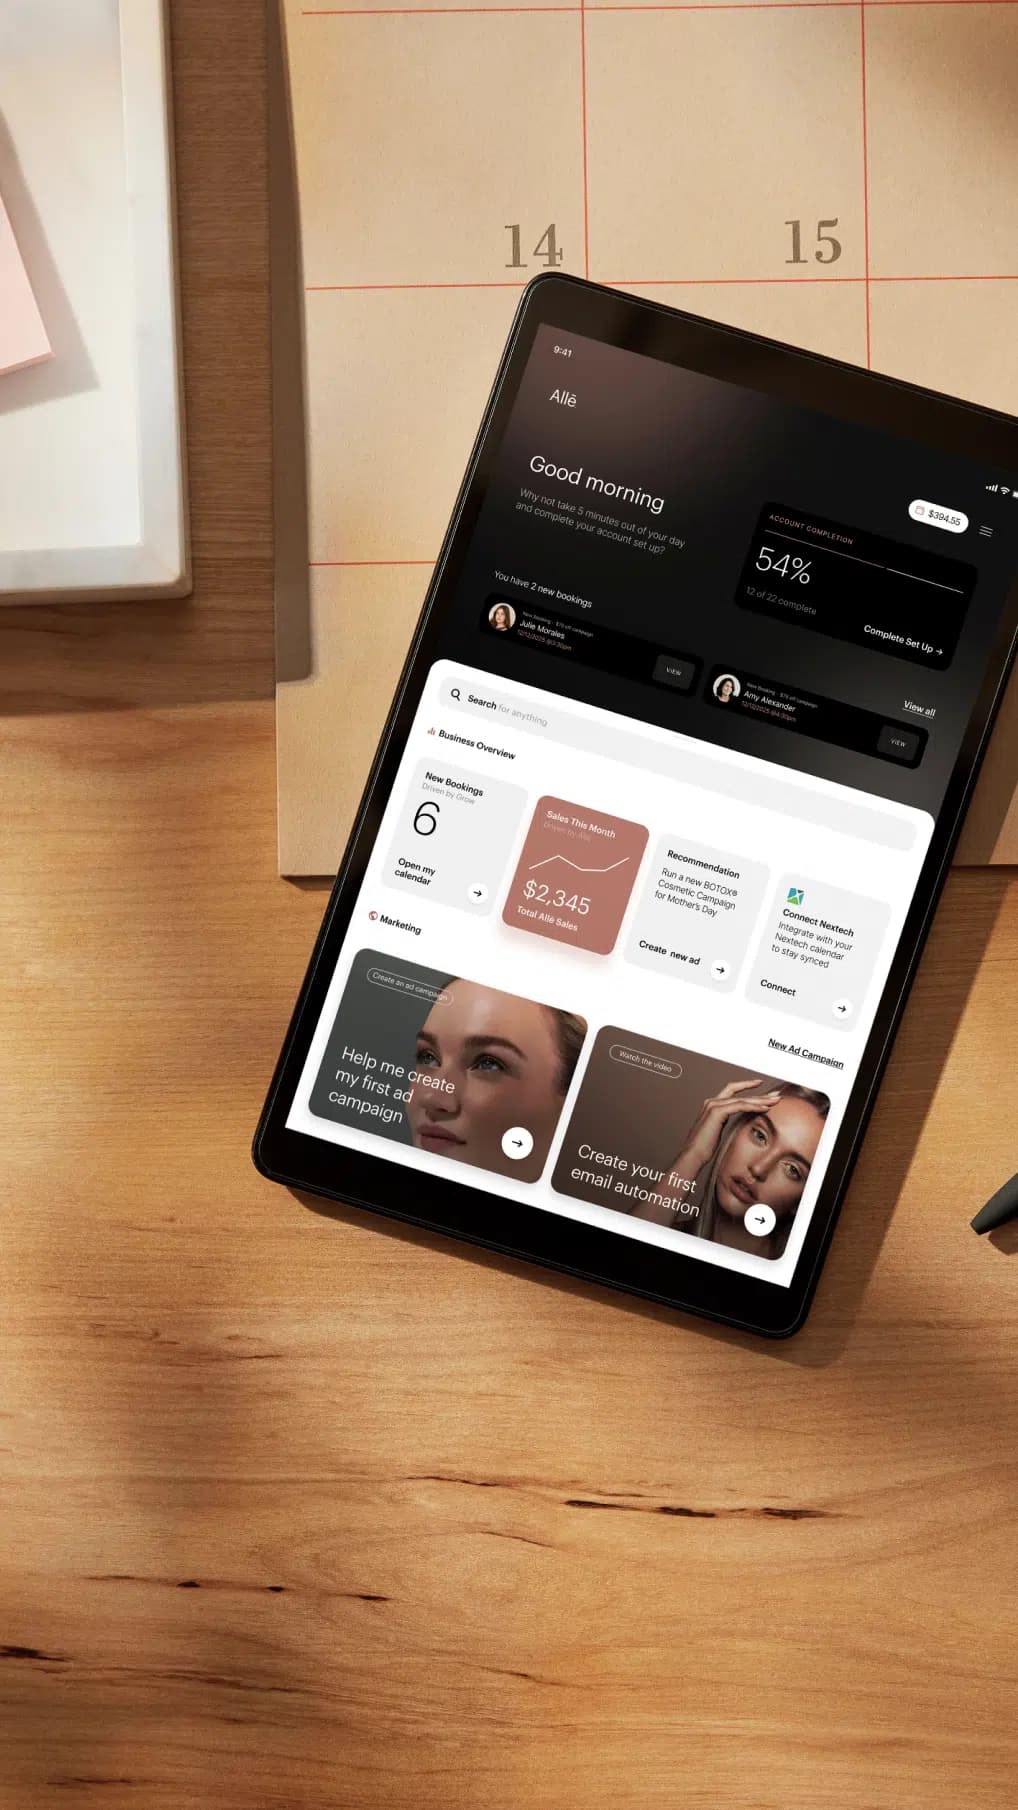
The canonical knowledge layer for AI native enterprise systems. Definitional pillars, named frameworks, live benchmarks, and field reports · built from real engagements at GE Aerospace, Allergan Aesthetics, Tiger BioSciences, GE Vernova, and Ross J Barr.
Written for senior buyers · No filler · Cite as you wish
69
Field guides
4
Topical clusters
1
Live benchmark
Weekly
Cadence
Start here · The four definitional pillars
04 / 04
What Is a Brand Operating System?
The connected set of decisions, components, and rules that lets every team ship one coherent brand.
ReadWhat Is a Brand Sprint?
A fixed timebox engagement that compresses a quarter of brand work into four to eight weeks.
ReadWhat Is AI Search Visibility?
Whether your brand surfaces when users ask ChatGPT, Perplexity, Claude, and Gemini about your category.
ReadWhat Is an AI Product Design Agency?
An agency that designs, builds, and operates AI native product surfaces. Distinct from a traditional design studio.
ReadBrowse by cluster
Four clusters. One canonical knowledge layer.
Every field guide on this page belongs to one of four topical clusters. Each cluster has a definitional pillar, supporting pages, comparisons, and (where it applies) a named framework.
AI Search Visibility
15 pages
How AI engines cite brands.
The AI Visibility Stack, the Citation Index, the Brand AI Scanner, four per engine deep dives, GEO vs SEO, six industry pillars.
Brand Operating Systems
9 pages
How modern brands operate at scale.
The Brand Operating System Framework, the definitional pillar, comparison and implementation guides, plus the 30 item checklist.
Industry & Regulated
9 pages
AI Visibility and software, per vertical.
AI Visibility for Aerospace, Biotech, Medical Devices, Healthcare, Energy, and the regulated umbrella · plus the matching software-development field guides.
POV & Frontier
4 pages
Where the work is going.
Long form essays on AI native operations, regulated product UX, the AI infrastructure buildout, and the shifts that change the work.
September 16, 2026 · 8 min read
How to Choose an AI Agent Framework
A year ago the framework you picked barely mattered. Every demo was one agent calling a few tools, and you could rewrite it in an afternoon. That is over. As teams move from demos to production, the framework decides how the agent holds state, where a person can step in, and what you can see when it fails, and rewriting it becomes a quarter, not an afternoon. Five names carry most of the weight right now: LangGraph, a low level framework for long running stateful agents; CrewAI, a standalone framework for role based crews; the OpenAI Agents SDK, released March 2025 as the successor to the experimental Swarm and provider agnostic across 100 plus models; Google ADK, a code first toolkit for teams inside Google Cloud; and the Microsoft Agent Framework, which folded AutoGen and Semantic Kernel into one path at its October 1, 2025 preview and sent both predecessors to maintenance mode. Which is best is the wrong question. The four traits that separate a demo from a system, and how to pick the one you can leave.
69 insights




Bttr. Field Brief
The brief Bttr. writes for senior buyers.
Monthly. One field guide worth your time on Brand Operating Systems, AI search visibility, and the infrastructure buildout. Written by Donny Smith. No filler.
We design, build, and run digital systems for the science, aerospace, and biotech industries.